Indexing and OCR
Updated on October 22, 2026
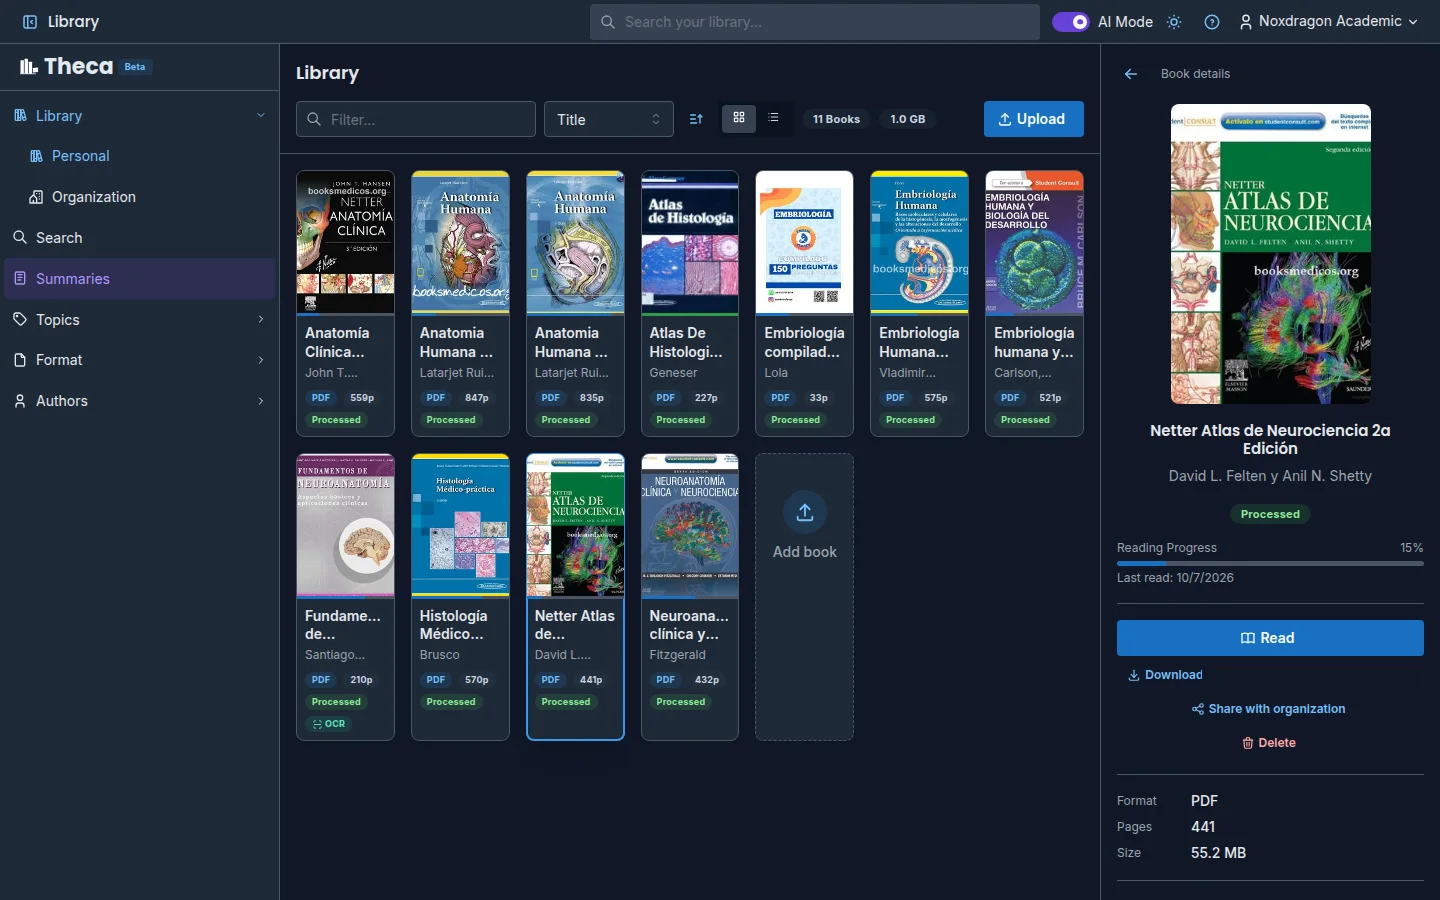
Before you can search a book or use it in a summary, Theca has to process it. This happens automatically after every upload, and here's what goes on in the meantime.
What processing does
Theca extracts the book's text, splits it into chunks and builds an index that lets you find passages by their idea even if you don't remember the exact words. Along the way it detects formulas and chemistry in PDFs. Until it's processed, a book can only be read and downloaded.
Automatic OCR for scanned PDFs
If a PDF is just images of pages with no text layer (a photocopy, for example), Theca detects it and runs optical character recognition (OCR) on its own. While it works, the book shows Extracting… with its live progress (for example, Extracting… 40/120).
When it finishes, the book is searchable like any other and carries the OCR badge. OCR takes longer than normal processing, especially on long books.
If OCR finds no usable text, the status changes to Scanned, no text. You can still read and download the book, and try again with Extract text (OCR) in the detail panel. If you've just tried, the button shows how long until you can use it again (OCR in …).
What each status means
- Processing — indexing is in progress; it may show the progress (for example,
Processing 4/10). - Extracting… — OCR in progress.
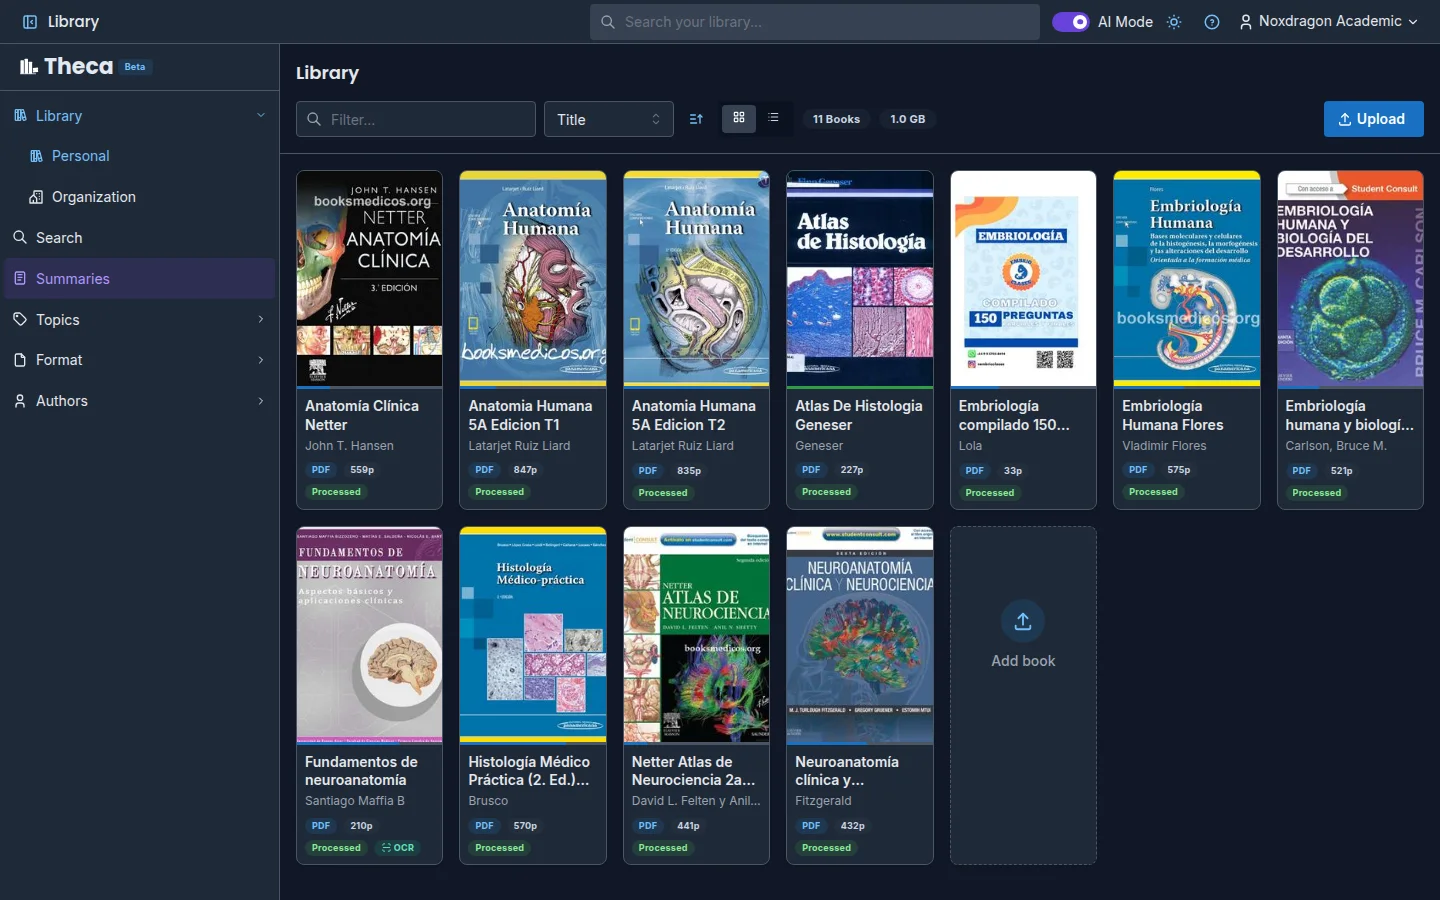
- Processed — ready for search and summaries.
- Not processed — the book hasn't been processed yet. Click Process in its panel or Process all in the toolbar.
- Scanned, no text — no text was found to index.
- Stuck — processing has gone too long without progress and nothing is working on the book.
- Error — retry — something went wrong.
Books that can't be searched yet are grouped under Not processed in the sidebar.
A stuck book always has a way out
If a book is Stuck or shows Error — retry, open its detail panel:
- Retry puts it back in the queue.
- Extract text (OCR) also appears on stuck books, in case the problem was a scan.
If the error keeps happening, download the file and check that it opens properly on your device.
Content badges
- OCR — the text was recognized from a scan.
- Formulas — the book contains recognized math or chemistry notation. In the PDF reader you can see it rendered in the Formulas & chemistry panel.
Frequently asked questions
How long does processing take? A few minutes for a typical book. Very long books and those that go through OCR take longer.
Do I have to start OCR myself? No. Theca runs it automatically when it detects a scanned PDF. The Extract text (OCR) button is for trying again.
Can I read a book while it's being processed? Yes, at any time.
What about read-only books? Books above your plan's storage can be read, downloaded and deleted, but not re-processed. See Plans and limits.
Next step
- Search your library — how to search once your books are processed.
- Highlights and formulas — the reader's scientific notation panel.
- Your library — statuses and badges at a glance.